Notes on building AI systems that ship.
Agentic architecture, RAG, eval-driven development, and what actually breaks in production. Written from inside the build, not after a demo.
I swapped my eval judge for a System-1 model. Here is what I'm testing.
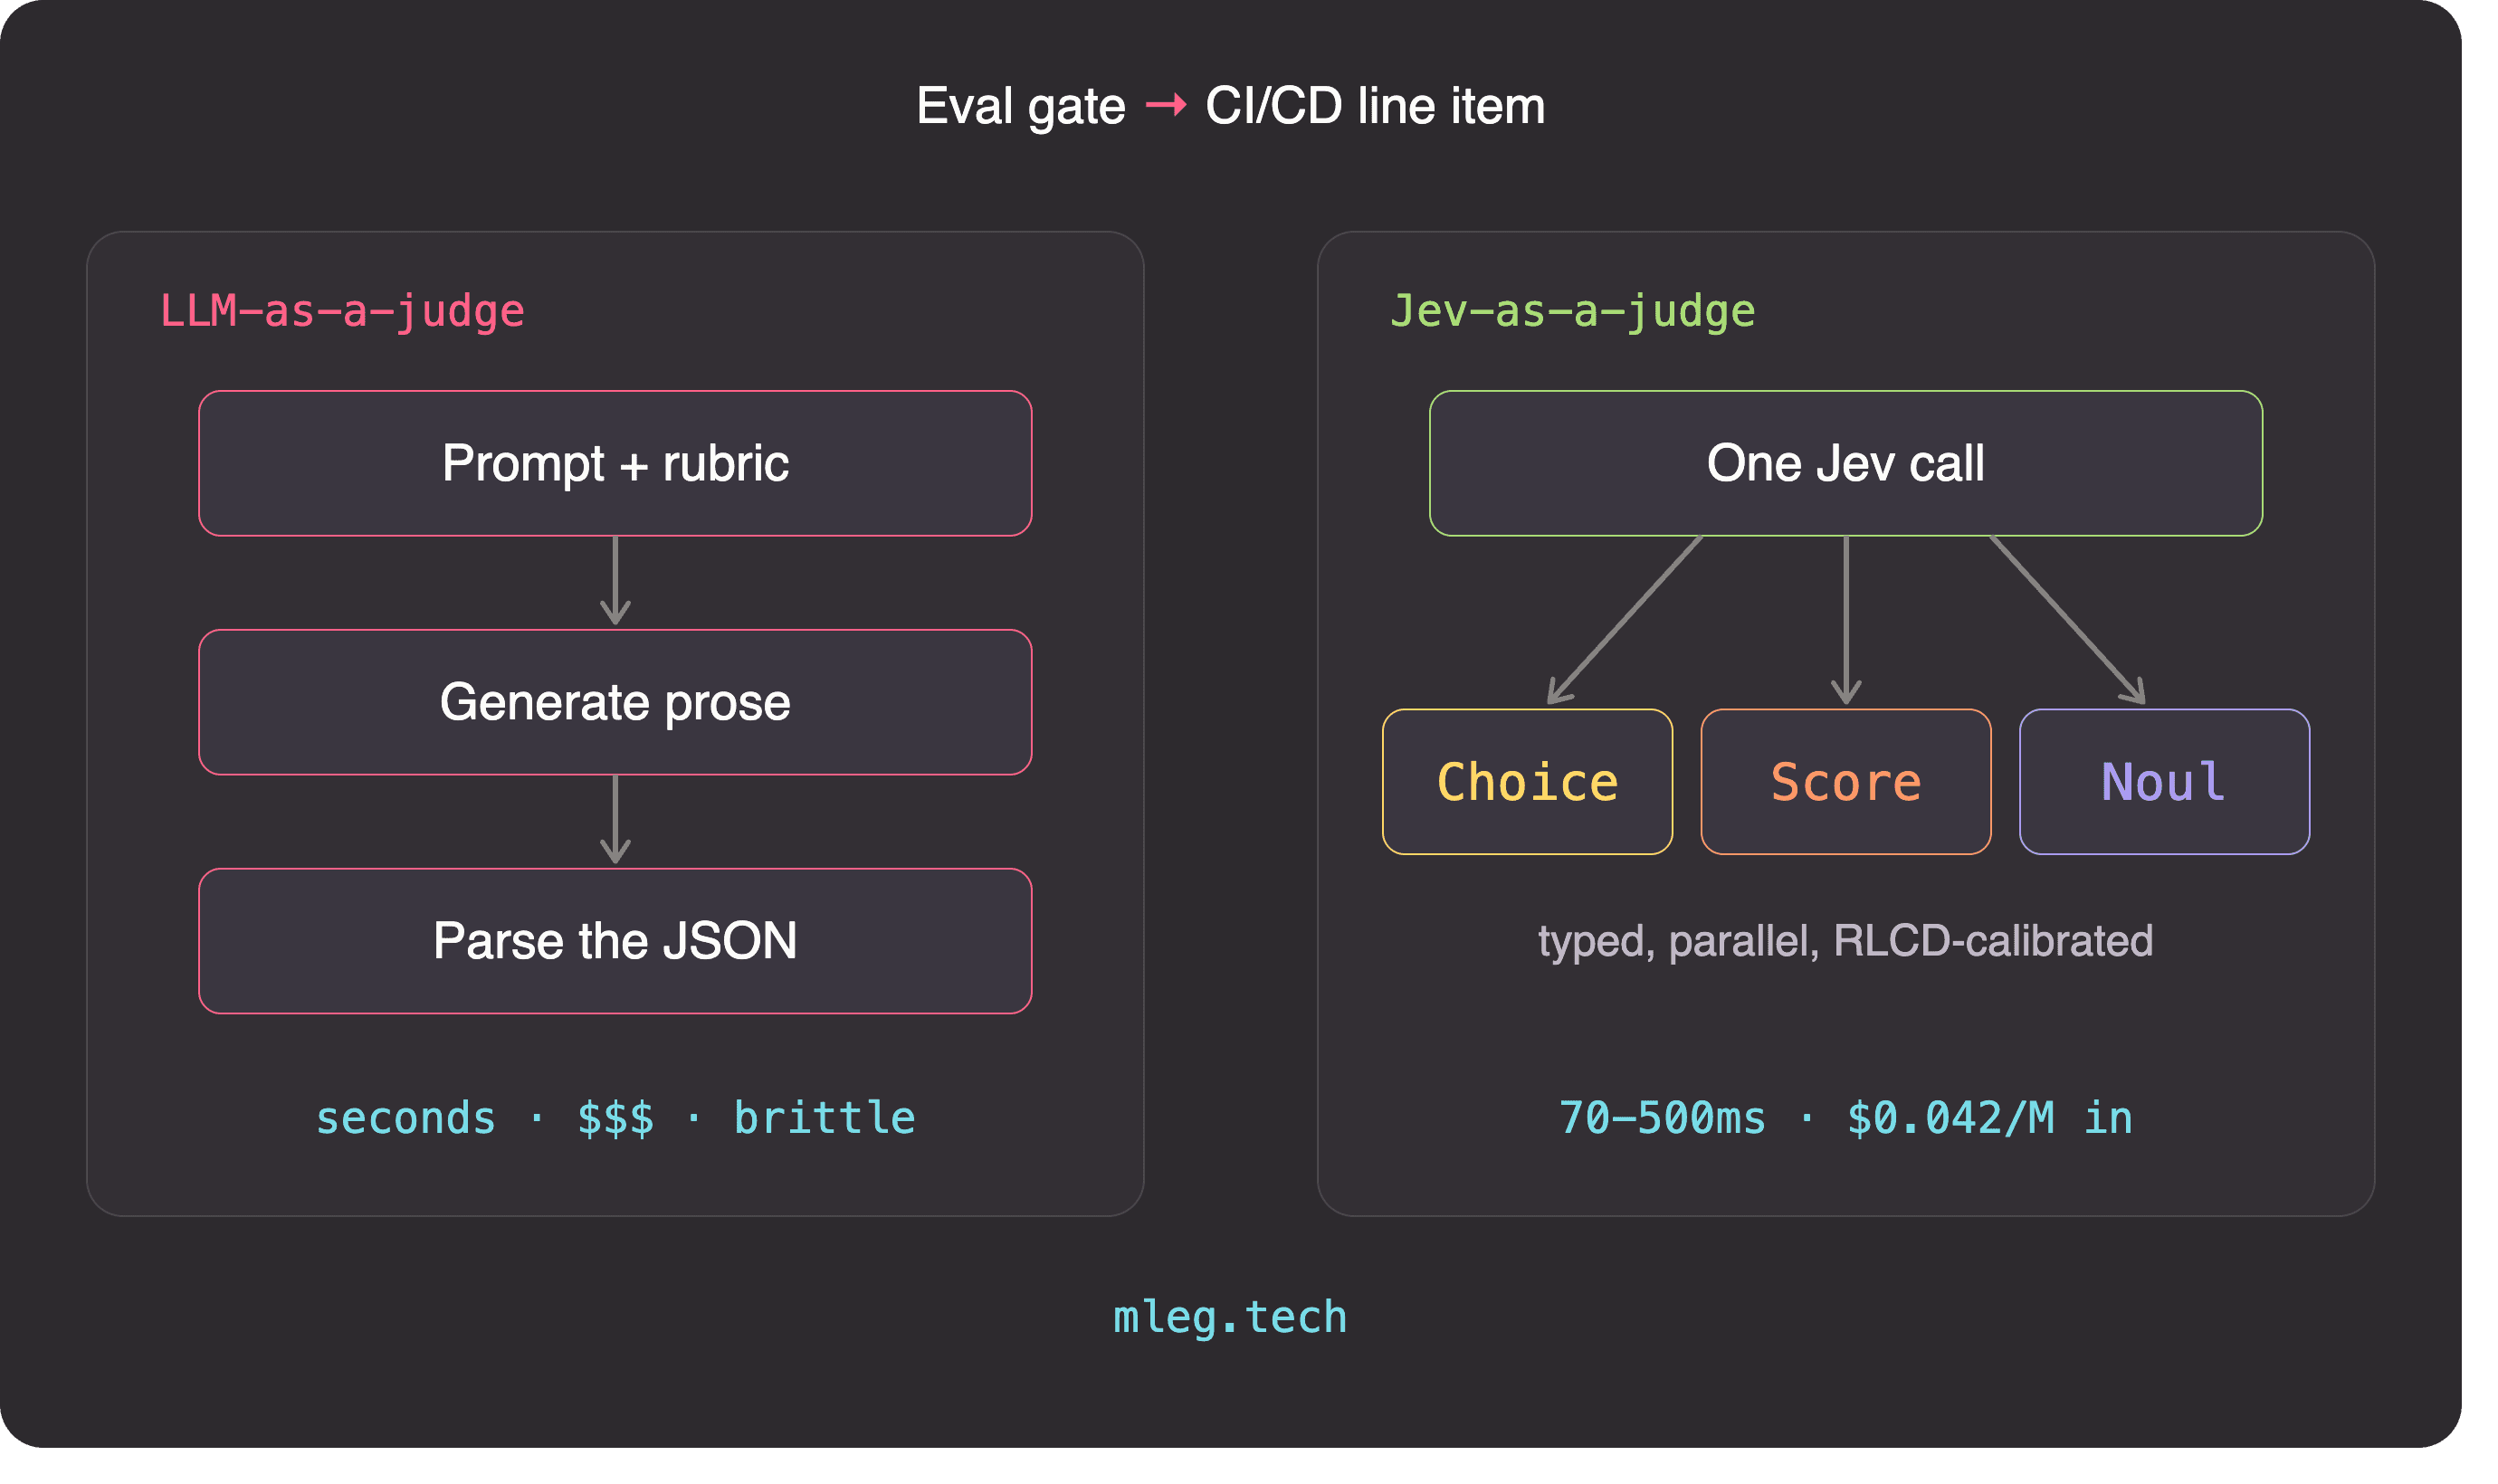
I'm running Jev, TypeSafe AI's textless System-1 model, as the judge in my eval harnesses to see if evals can run on every commit instead of once a night.
Your eval dashboard is a crime scene photo
Your agent hallucinates a contract clause. Sends it to a customer. Then, an hour later, a dashboard somewhere turns red.
AI Observability Isn't APM With Extra Steps
Uptime and latency can't tell you if an agent's output is correct. Why AI observability needs a different kind of tooling than the APM stack you already have.
Bedrock Agents Classic Just Closed to New Customers. Here's What That Actually Means.
Bedrock Agents is now Classic, closed to new customers, and in maintenance mode — what AgentCore actually changes, and what it means if you're already running agents in production.
What Actually Breaks When You Put LangGraph Agents in Production
Reducer bugs, state bloat, and the deep-merge fix that took a full day to trace — lessons from running multi-agent workflows on AWS Bedrock at scale.
Chunking Strategy Matters More Than Your Embedding Model
Why fixed-size chunking quietly tanks retrieval quality, and what content-hash dedup buys you at scale.
LLM-as-a-Judge: Building Quality Gates Into CI/CD
How an eval pipeline caught stale-context regressions before they reached production, and what it cost to build.
Bedrock + AppSync: A GraphQL Front Door for Agentic Workflows
Decoupling frontend from backend on multi-step AI processes without losing type safety or introducing polling.